Cerebras Plans 8x To 10x Manufacturing Scale-Up For AI Inference
Cerebras chief executive Andrew Feldman said the company plans to scale manufacturing capacity by 8x to 10x this year and claimed its systems can run inference 10, 15, 20 or 30 times faster than GPUs. The interview-led source named customers including AlphaSense, Cognition AI, OpenAI, Block and GlaxoSmithKline, The public record still lacks third-party benchmark methodology.
Cerebras is making inference speed the centre of its AI compute pitch, with chief executive Andrew Feldman saying the company plans to scale manufacturing capacity by 8x to 10x this year as agentic AI workloads increase demand for fast model responses.
The public record still lacks independently audited benchmark results for the performance claims.
Cerebras Plans 8x To 10x Manufacturing Capacity Growth
Feldman said Cerebras plans to scale manufacturing capacity by eight to 10 times this year.
He linked that expansion to data-centre buildout, next-generation chip and system design, and growing demand from customers using inference for agents and coding workflows.
The company is positioning inference as a hardware bottleneck as AI systems make more sequential calls and reason over longer context windows.
Feldman said faster inference can let customers search across more documents and run more reasoning iterations before returning an answer.
The article named AlphaSense as a customer using speed to search over more documents.
It also said customers include Cognition AI, OpenAI in coding flows, Block for financial agents, GlaxoSmithKline for enterprise deployments and European high-performance computing centres.
Feldman Claims 10, 15, 20, 30 Times Faster Inference
Feldman said Cerebras is "10, 15, 20, 30 times faster than GPUs" for inference.
That is a vendor performance claim from the company's chief executive; independent benchmark methodology, test configuration, model details and third-party validation remain outside the public record.
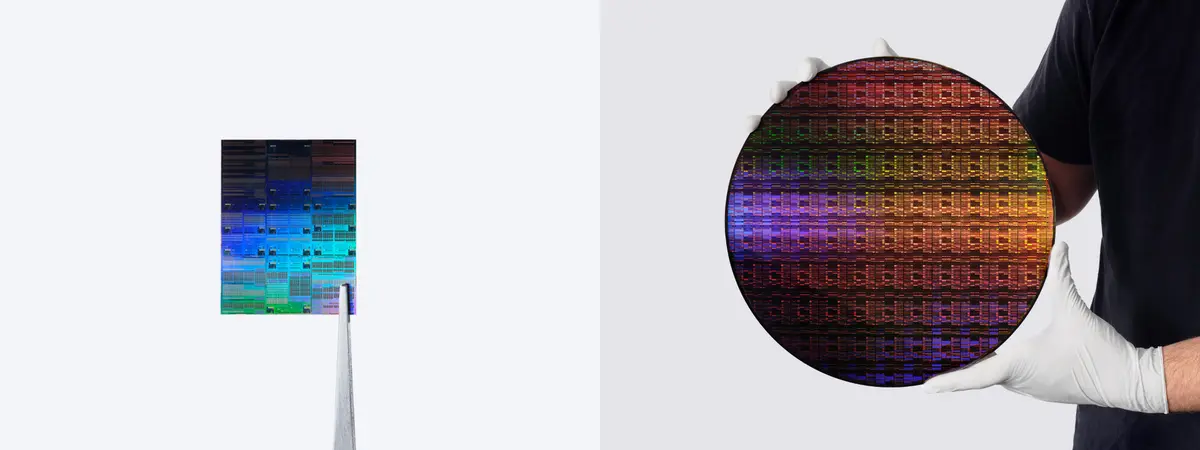
The technical argument centres on Cerebras's wafer-scale architecture.
Feldman said the design keeps model weights in on-chip SRAM, which the company presents as a way to avoid memory constraints that slow conventional GPU systems.
RAISE Summit 2026 Interview Names Customers But Not Orders
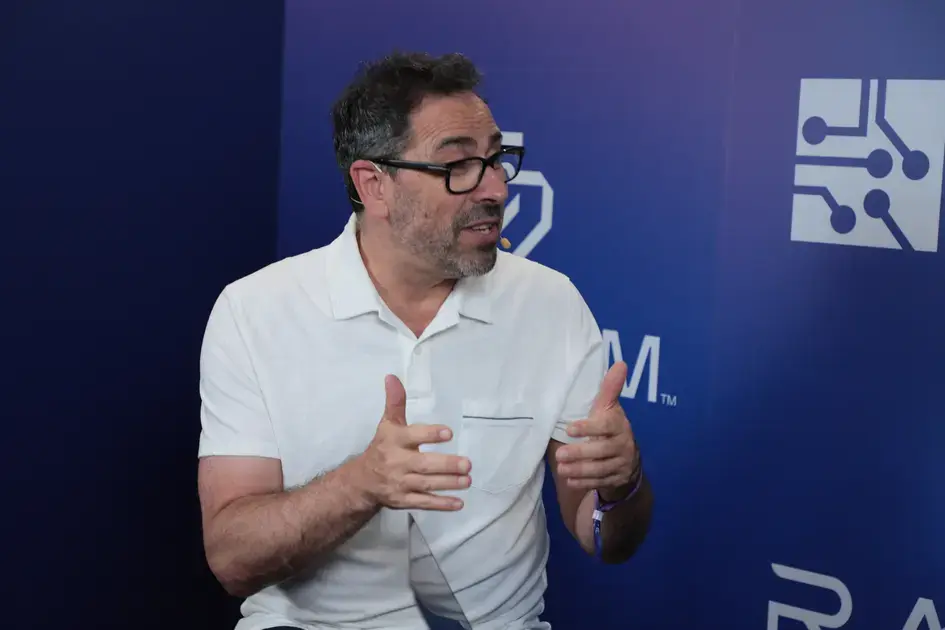
Feldman spoke with John Furrier and Dave Vellante at the RAISE Summit.
The discussion covered Cerebras's IPO milestone, inference speed, European data-centre buildout and manufacturing scale, The public record still lacks IPO timing, production-site names, wafer supply commitments or signed order totals.
The article disclosed that theCUBE was a paid media partner for the RAISE Summit event and said sponsors did not have editorial control over the content.
The public record lists the source useful for company strategy and named-customer claims, but not enough to treat the speed comparison as independently verified.
Independent benchmark methodology, exact manufacturing partners, named manufacturing sites, signed order volumes and a timetable for the IPO milestone remain outside the public record.