Crusoe Adds Serverless Fine-Tuning To AI Infrastructure Platform
Crusoe added managed fine-tuning and inference services for open-weight models inside Intelligence Foundry. The launch moves its AI infrastructure pitch beyond rented GPU access, while prices, named customers and verified savings remain outside the public record.
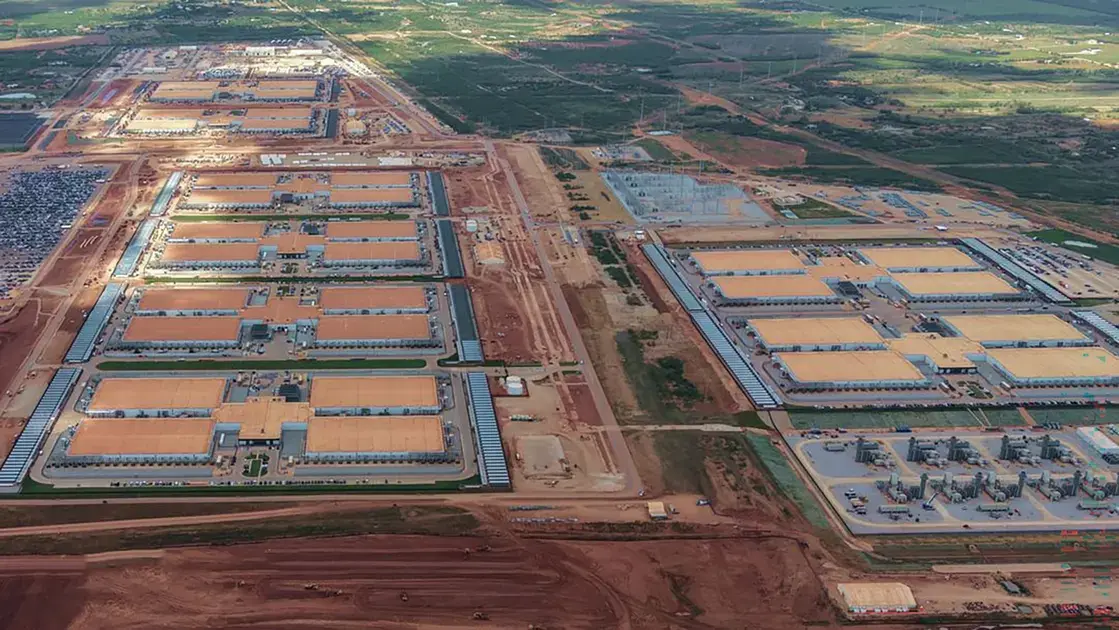
Crusoe is moving its AI infrastructure pitch beyond rented GPU access by adding managed fine-tuning and inference services for open-weight models, Data Center Knowledge reported.
The new Serverless Fine-Tuning and Self-Serve Deployments services will sit inside Intelligence Foundry.
They are aimed at teams that want to adapt open-source foundation models, deploy managed inference endpoints or export fine-tuned model weights without provisioning GPU clusters directly.
Intelligence Foundry Adds Serverless Fine-Tuning
The fine-tuning service lets customers bring data to open-weight foundation models and receive completed weights in the open . safetensors format.
Customers can deploy those weights on the same platform or move them elsewhere, making portability part of the product claim.
Erwan Menard, senior vice president of product, told Data Center Knowledge that enterprises are moving towards model ownership instead of relying only on proprietary APIs.
AI-native companies are feeding production data back into open-weight models regularly as they try to improve performance and reduce inference costs.
Demand for continuous fine-tuning is accelerating faster than expected, particularly among teams building production AI agents where model predictability and data ownership affect procurement decisions, according to Data Center Knowledge.
The platform currently supports a curated library of open-weight models including Qwen, DeepSeek, Gemma and GPT-OSS.
IDC Points To Competition Beyond GPU Access
Dave McCarthy, research vice president at IDC, said raw GPU access was the dominant story for about 18 months but is no longer enough by itself.
Enterprise buyers are looking at fine-tuning pipelines, evaluation, deployment tooling and inference optimisation as one system.
Providers that only sell chips risk becoming interchangeable.
McCarthy framed the launch as part of a wider shift in AI data centre competition from capacity supply towards full model-lifecycle platforms.
Portability is another procurement issue.
McCarthy said portability is no longer optional for enterprise buyers, while Menard said organisations using open-weight models increasingly expect to keep their fine-tuned weights rather than stay locked to one inference platform.
General Availability Is Scheduled For Next Week
Both services are scheduled for general availability next week through Intelligence Foundry.
The fine-tuning charge will use a per-million-token model, while managed inference will be charged by GPU hour.
The inference service uses Nvidia H100 and H200 GPUs for managed endpoints.
The launch also includes automatic job restarts, checkpoint saving during training and billing that stops when a model stops improving.
Named customers, per-million-token prices, GPU-hour rates, utilisation targets, benchmark methodology, service-level terms and customer-verified cost savings for the new fine-tuning and inference services remain outside the public record.