OpenAI Rolls Out GPT-Live For ChatGPT Voice Without API Timing
OpenAI said GPT-Live will let ChatGPT Voice listen and speak at the same time, with GPT-5.5 handling harder search and reasoning in the background. The company cited more than 150 million weekly Voice and Dictation users while API timing, video support dates and independent benchmark validation remain outside the public record.
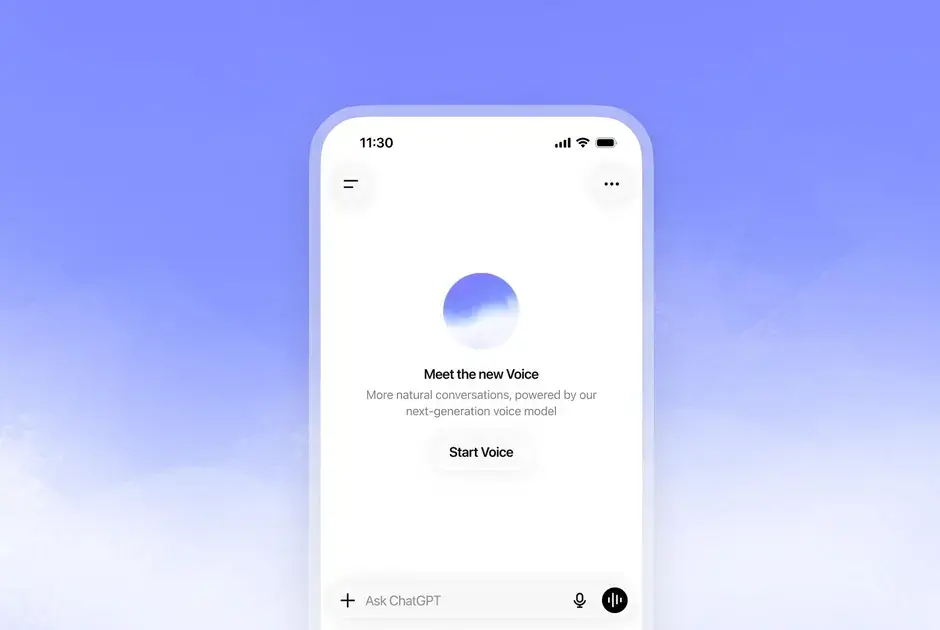
GPT-Live is taking over ChatGPT Voice as a full-duplex model that OpenAI says can listen and speak at the same time while handing harder questions to GPT-5.5 in the background.
The global rollout starts for ChatGPT users, while API launch timing, video support and screen-sharing availability at launch remain outside the public record.
GPT-Live Rolls Out To ChatGPT Voice Users Globally
The company is beginning to roll out two versions of the new system, GPT-Live-1 and GPT-Live-1 mini, to ChatGPT users globally.
GPT-Live-1 will become the default model for ChatGPT Voice on Go, Plus and Pro plans, while GPT-Live-1 mini will become the default for Free users.
The rollout covers ChatGPT on iOS, Android and ChatGPT.com.
The company plans to bring GPT-Live to the API soon, and the announcement directed developers and enterprises to a notification form rather than a release date.
The announcement framed GPT-Live as a change in voice architecture rather than only a new interface.
Earlier cascaded systems chained speech-to-text, language-model response and text-to-speech models, an approach the announcement said could lose information across models and produce slow, stilted responses.
Full-Duplex Voice Lets The Model Listen And Speak Together
GPT-Live uses a full-duplex architecture, meaning the model continuously processes input while generating output.
The company said the model can decide many times per second whether to speak, keep listening, pause, interrupt or use a tool.
That design is meant to reduce one of the common limits in voice assistants: rigid turn-taking.
Turn-based voice models wait for a user to stop speaking before responding, and silence-based turn detection can mistake a short pause or background noise for the end of a turn, according to the announcement.
In the new ChatGPT Voice experience, users can interrupt with a question, pause while thinking or ask ChatGPT to stay quiet and listen.
The company also said the model can acknowledge that it is listening with short phrases such as "mhmm" or "got it", and that it has remastered the nine distinct voices in ChatGPT for GPT-Live.
GPT-5.5 Handles Search And Reasoning Behind Voice Replies
GPT-Live keeps the live audio exchange separate from heavier tasks.
For questions involving search, reasoning or more agent-like work, OpenAI said GPT-Live can hand the request to another model such as GPT-5.5 while the spoken session continues.
At launch, GPT-Live will use GPT-5.5 in the background.
The announcement also said GPT-Live-1 Instant and GPT-Live-1 mini use GPT-5.5 Instant, while GPT-Live-1 Medium and GPT-Live-1 High use GPT-5.5 Thinking with medium and high reasoning effort.
The voice mode can now show rich visual cards during spoken conversations for topics such as weather, stocks and sports.
Voice also continues to support search, memory, images and file uploads.
OpenAI Cites 150 Million Weekly Voice And Dictation Users
The company said more than 150 million people each week talk to ChatGPT using features such as Voice and Dictation.
In matched 5-10 minute human evaluations covering preference, turn-taking, interruptions, conversational flow and naturalness, GPT-Live-1 and GPT-Live-1 mini were strongly preferred over Advanced Voice Mode, according to the announcement.
Those results were presented as internal evaluations.
The company said GPT-Live-1 outperforms Advanced Voice Mode on GPQA, BrowseComp and an internal tau3-Voice Telecom variant, while independent benchmark validation and customer-level enterprise deployment data remain outside the announcement.
The safety section also stays inside the company's own testing boundary.
GPT-Live adds audio-native evaluations, synthetic audio testing, internal red-teaming, safeguards for higher-risk conversations, teen protections and voice-impersonation limits based on predefined voices, according to the announcement.
API release timing, developer pricing, independent benchmark results, enterprise customer deployments, video or screen-sharing support dates and language-by-language quality data remain outside the public record.