IBM Research Tests Agent Routing On Cost, Latency And Accuracy
A Hugging Face post from IBM Research said model routing for enterprise AI agents should optimise cost, quality and latency together after AppWorld tests reversed a simple token-price comparison.
An IBM Research test found that the cheaper-looking AI model was not always the cheaper agent once caching, tool calls and execution time entered the bill.
In a Hugging Face post, IBM researchers argued that enterprise agents should route work using cost, quality, latency, compliance and reliability together rather than relying on a model's sticker price.
AppWorld Costs Reversed The Sticker-Price Assumption
IBM Research said in the Hugging Face post that Sonnet cost $79 in total, or $0.19 per task, across 417 AppWorld Test Challenge tasks using the same CodeAct agent, while GPT-4.1 cost $155, or $0.37 per task.
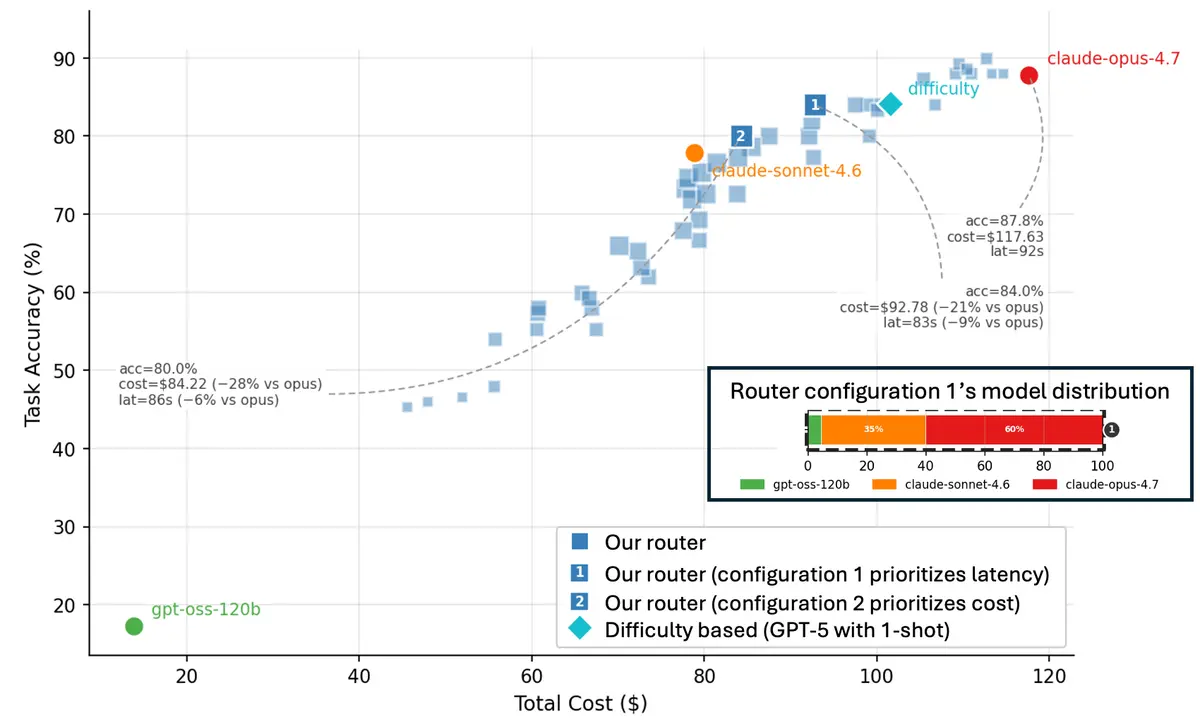
IBM Research also said a later latency-focused router example reached 84% accuracy for $93 and 83s, with a 21% cost reduction and 9% latency reduction compared with Opus alone and a 4% accuracy drop.
Independent benchmark validation sits outside the public record for either comparison.
Caching changed that bill.
Agent workloads can reuse large parts of the same context across steps.
Agent workloads can reuse large parts of the same context across steps, and the authors attributed Sonnet's advantage to lower cache-read pricing that benefited from that pattern.
Companies deploying multi-step agents therefore have to compare the cost of the full workflow rather than the nominal rate for a single prompt.
The comparison depends on the workload, not only the model brand.
A router that looks only at a price sheet can choose the cheaper-looking model while missing cache-read economics, repeated context and the number of intermediate tool calls that determine the final bill.
Routing Difficulty Appears After Execution Starts
The authors argued that routing by task difficulty breaks down when the workload looks simple at the front door but expands during execution.
A contract-summary request, for example, can trigger retrieval, compliance checks, tool calls and rounds of revision, while a technical prompt may be handled efficiently by a specialised smaller model.
The production section names five routing criteria: cost, quality, latency, compliance and reliability.
It also lists enterprise constraints such as data residency, privacy rules and approved-model lists as conditions that can change the model choice for a task.
Latency adds another layer.
The authors identified routing overhead, hardware placement, endpoint load and cache warmth as variables that can dominate what a user experiences.
Routing once per task limits overhead, while routing at every step gives more flexibility but adds more decision points and operational complexity.
Routing therefore depends on more than the prompt presented at the start of a task.
The model is one input, but the serving endpoint, cache state, approved-model list and expected tool path can all change the answer before the user sees a response.
The mechanism is especially relevant for agents that call tools or retrieve documents over several steps.
The Hugging Face post says each extra step can change cache use, endpoint load and governance checks, so the first routing decision may not describe the whole workload.
IBM Research Tests An Optimisation-Based Router
The router section moved model choice away from classification and towards optimisation across cost, quality and latency.
IBM Research framed that optimiser as a way to search the trade-off space rather than rely on a single difficulty score.
The same section put optimisation overhead at roughly 6 ms and 2 kB of memory per task, limiting the risk that the router itself becomes a bottleneck.
A standard difficulty-based router landed in a similar accuracy range at higher cost, according to the comparison, because it did not search the broader trade-off space.
IBM Research said a follow-up post would provide more technical detail.
The published material did not include the router's full design, underlying configuration table or customer deployment results.